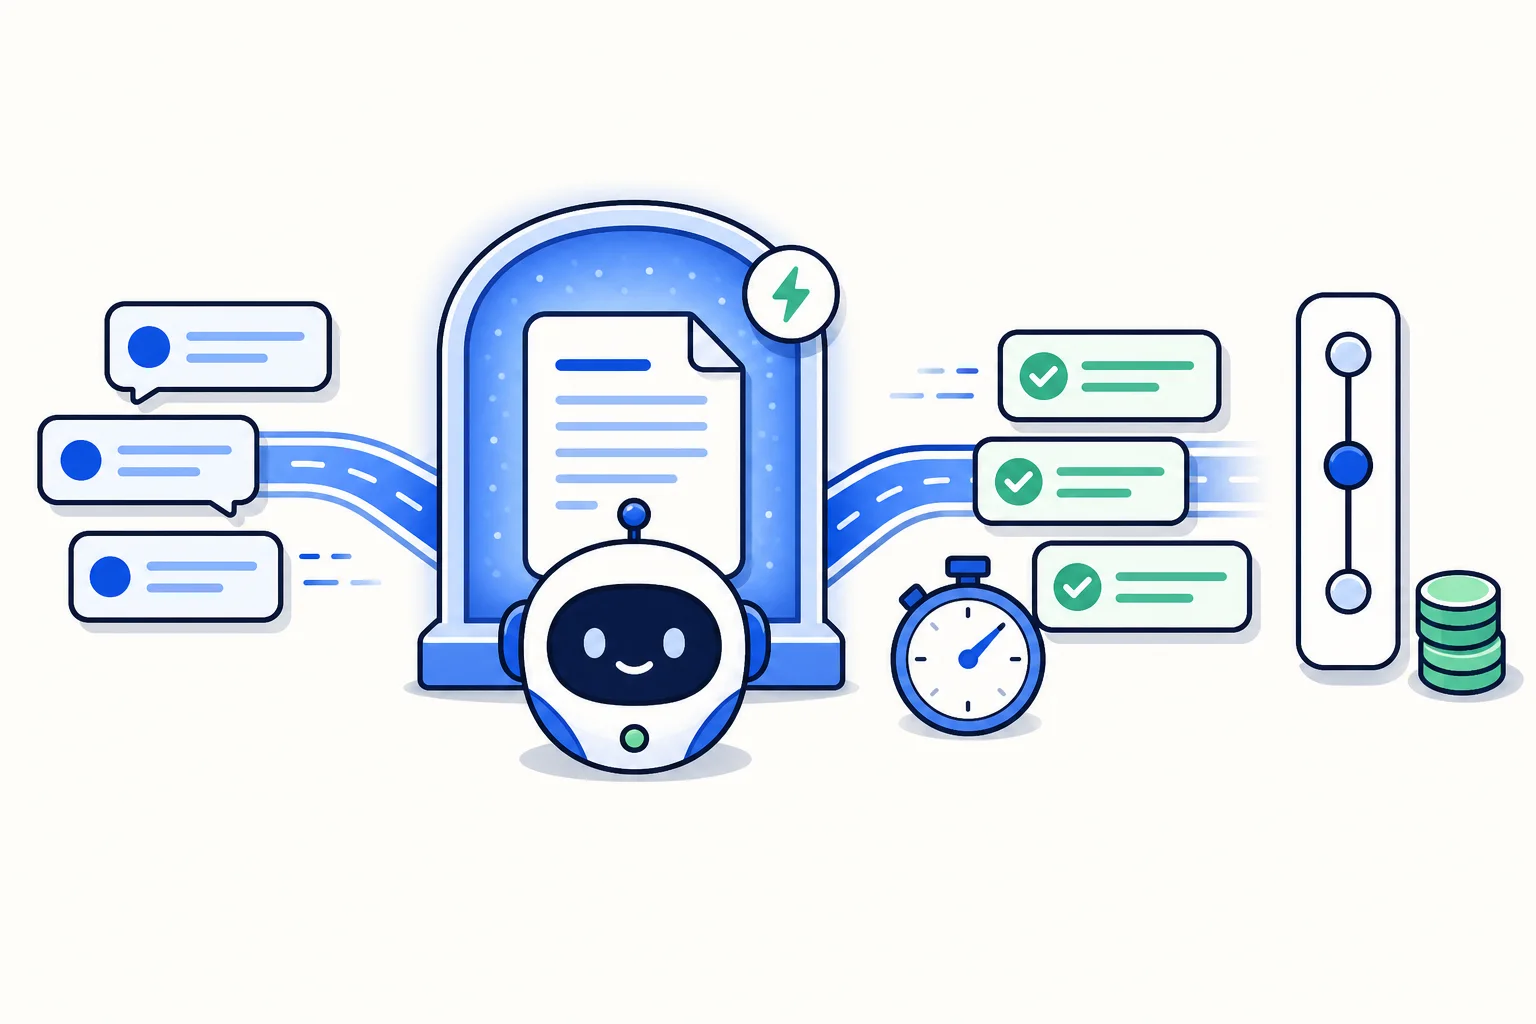
Every reply an AI agent writes starts with the same long preamble: who the agent is, how it should sound, what it knows about the business, what it must never do. That system prompt can run to thousands of tokens, and until now the model read all of it from scratch on every single message. HellouOne has shipped two changes that attack that waste directly. Each AI agent's system prompt is now cached with the model provider (Gemini), and the amount of reasoning effort an agent spends per reply is adjustable. The result is cheaper, faster replies without changing what the agent says.
How prompt caching works
A language model is billed and timed by the tokens it processes. When the first few thousand tokens of a request are identical from one call to the next, the provider can keep its processed form in a cache and skip the work the second time. The model still sees the full prompt; it just does not pay to re-read the part that has not changed. That is prompt caching, and it only helps if the repeated part is actually identical on every call.
That last condition is where the real engineering happened. HellouOne used to place per-turn context, such as the current conversation details, inside the system message. Every turn made the system message slightly different, so the cache never hit. The per-turn context has now been moved out of the cached system message into the part of the request that is expected to change. The stable part stays stable, the cache hits on every reply after the first, and the agent behaves exactly as before.
What it changes for reply speed and cost
Lower cost per reply. The cached portion of the prompt is billed at a reduced rate by the provider, and for agents with large knowledge in the system prompt that portion is most of the request.
Lower latency. Skipping the re-processing of the system prompt shortens the time to first token, which the customer experiences as a faster first reply.
No change in behaviour. The agent reads the same instructions and the same knowledge. Caching changes how the request is processed, not what it contains.
It compounds with volume. A line handling thousands of conversations a day repeats the same system prompt thousands of times; that is exactly the case caching was designed for.
Reasoning effort, per agent
The second change is a dial. Reasoning effort controls how much thinking the model does before it answers. More effort can help on genuinely hard questions; on the typical customer message, which is a question about hours, a price or an order, it mostly adds time and cost. HellouOne now sets reasoning effort per AI agent, low by default, and lets you change it in the agent editor or by asking LIA. A sales agent that handles nuanced negotiations can run at a higher setting; a front-desk agent answering the same twenty questions all day stays at low and answers faster for less.
Why this matters for a business budget
AI messages are metered on HellouOne plans, and the model cost behind them is what shapes those limits over time. Caching and the effort dial lower the cost of serving each reply, which is what makes generous AI message allowances sustainable and keeps the per-message price well below comparable alternatives. For the business, it means the AI agent can take on more of the conversation volume at the same budget, and reply faster while doing it.
How to use it in HellouOne
Caching is on for every AI agent; there is nothing to enable. The thing worth doing is keeping the system prompt stable: put the knowledge that rarely changes in the agent's prompt or knowledge base, and leave per-customer details to the conversation, which is how the editor is laid out. For reasoning effort, open the agent in the editor or ask LIA to show the current setting. Leave it at low for high-volume, well-defined jobs. Raise it for an agent whose conversations involve judgement, and watch reply time and AI message usage in Reports after the change. As with every agent edit, LIA proposes the change and you approve it, and the new setting becomes a version you can roll back.